04 · Data pipeline · Web
Books Price Intelligence
From scraped pages to a dataset you can trust — and an honest model on top.
Recorded from the running project
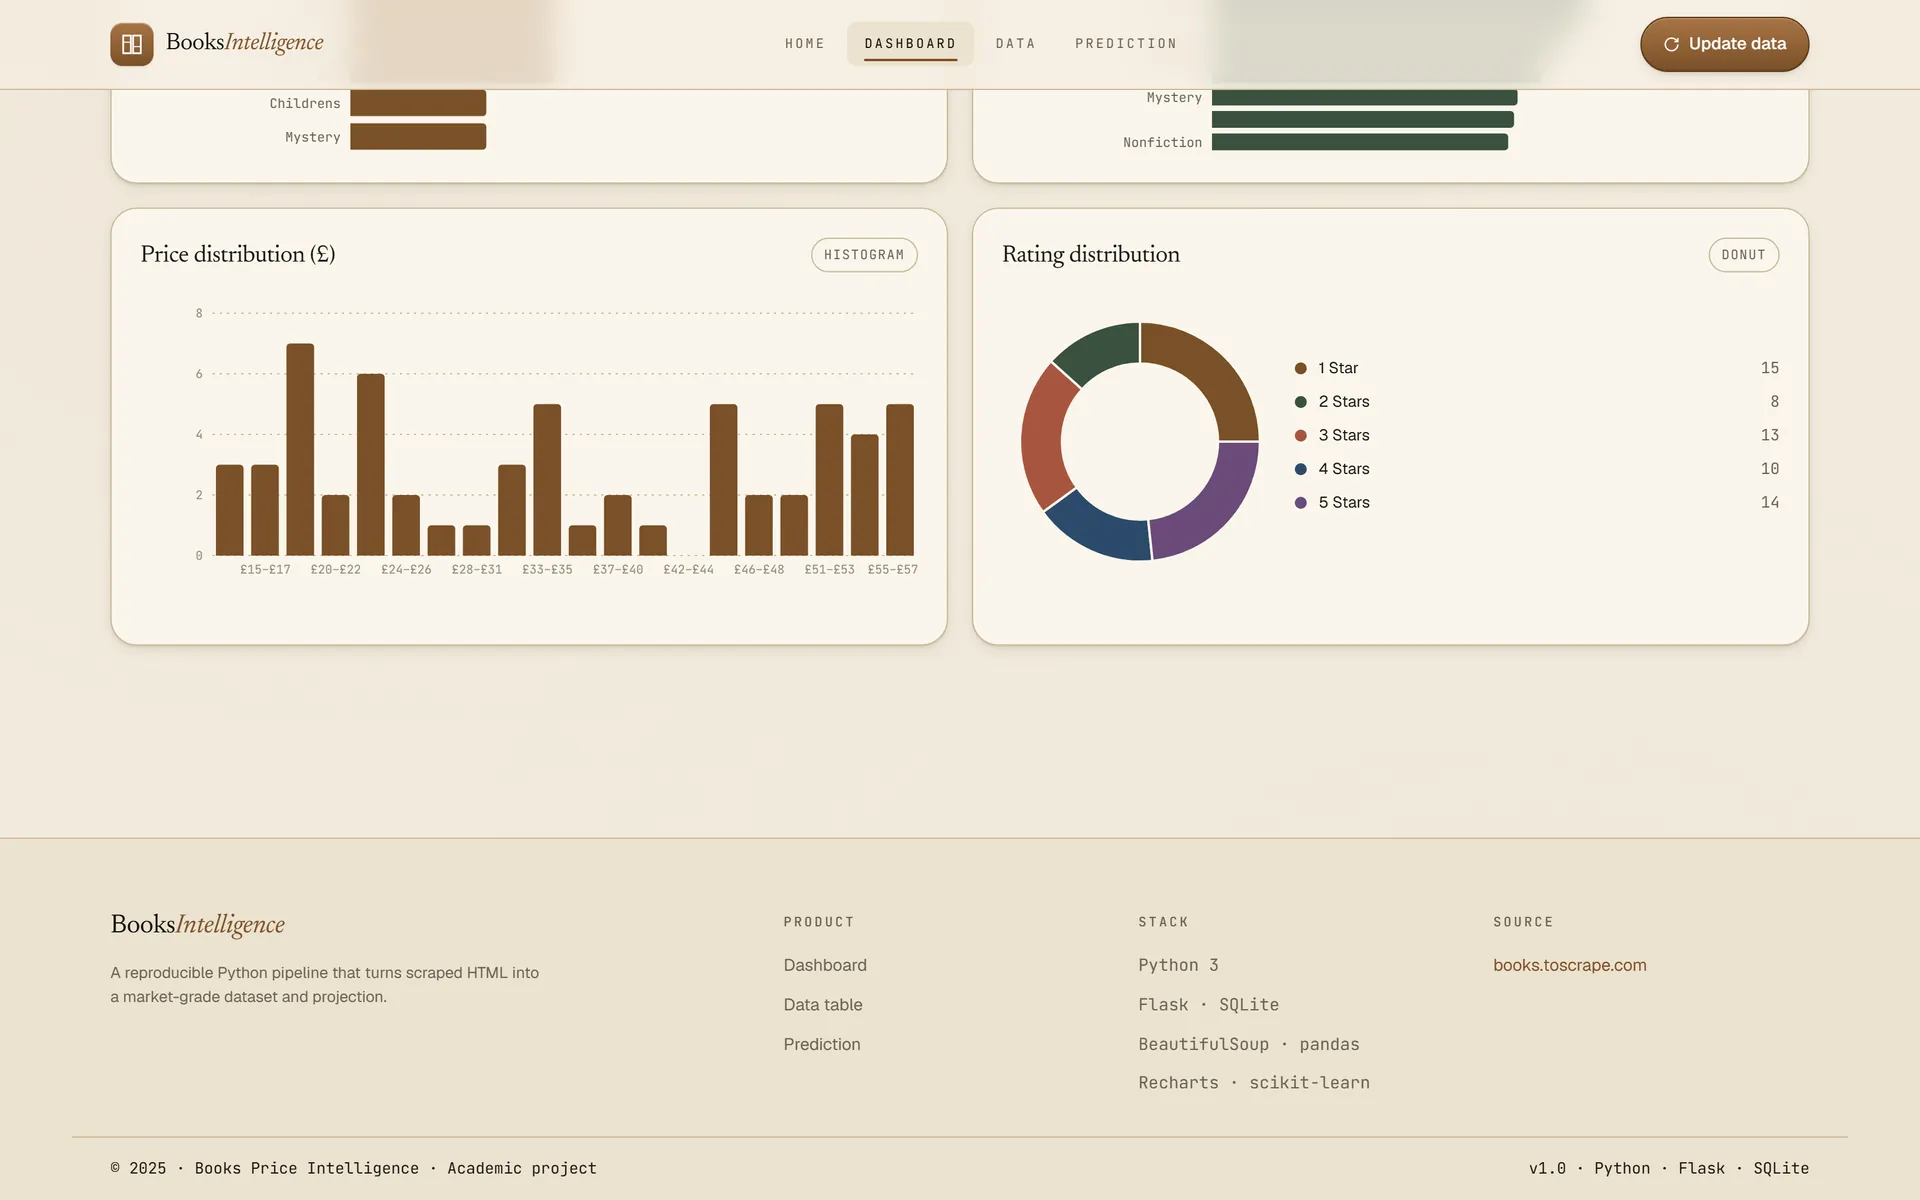
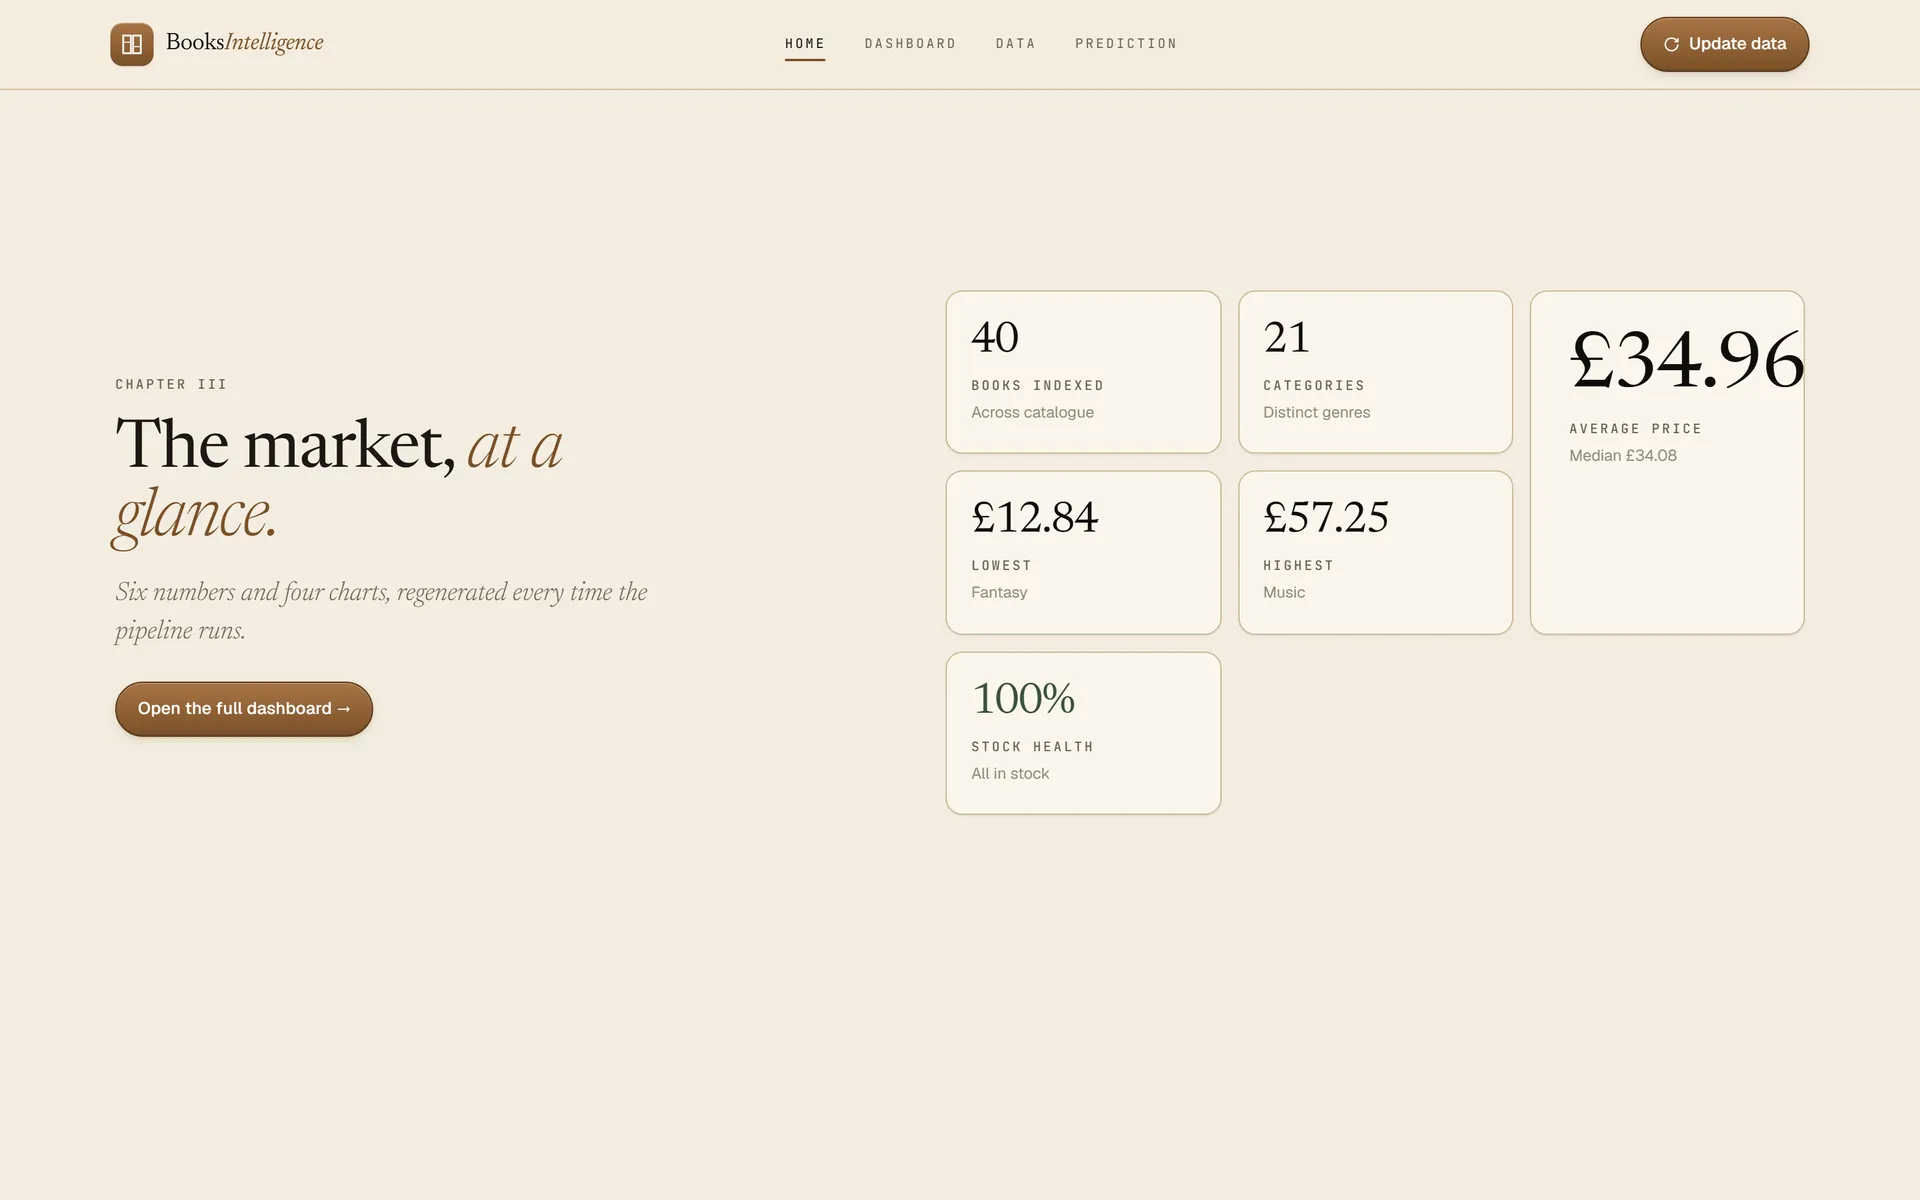
An end-to-end Python pipeline: scrape a public practice catalogue politely, clean it with pandas, store it in SQLite, serve it through Flask, and explore it in a React dashboard — with a linear-regression page that says plainly what it can’t predict.
What I built
- 01
A scraper for books.toscrape.com — a sandbox made for scraping practice — with a polite delay between requests and a descriptive User-Agent.
- 02
A cleaning stage (prices, word ratings, duplicates, nulls), SQLite storage and CSV export.
- 03
A Flask REST API with a live scrape trigger and progress polling, feeding a React + TypeScript dashboard with filters and charts.
- 04
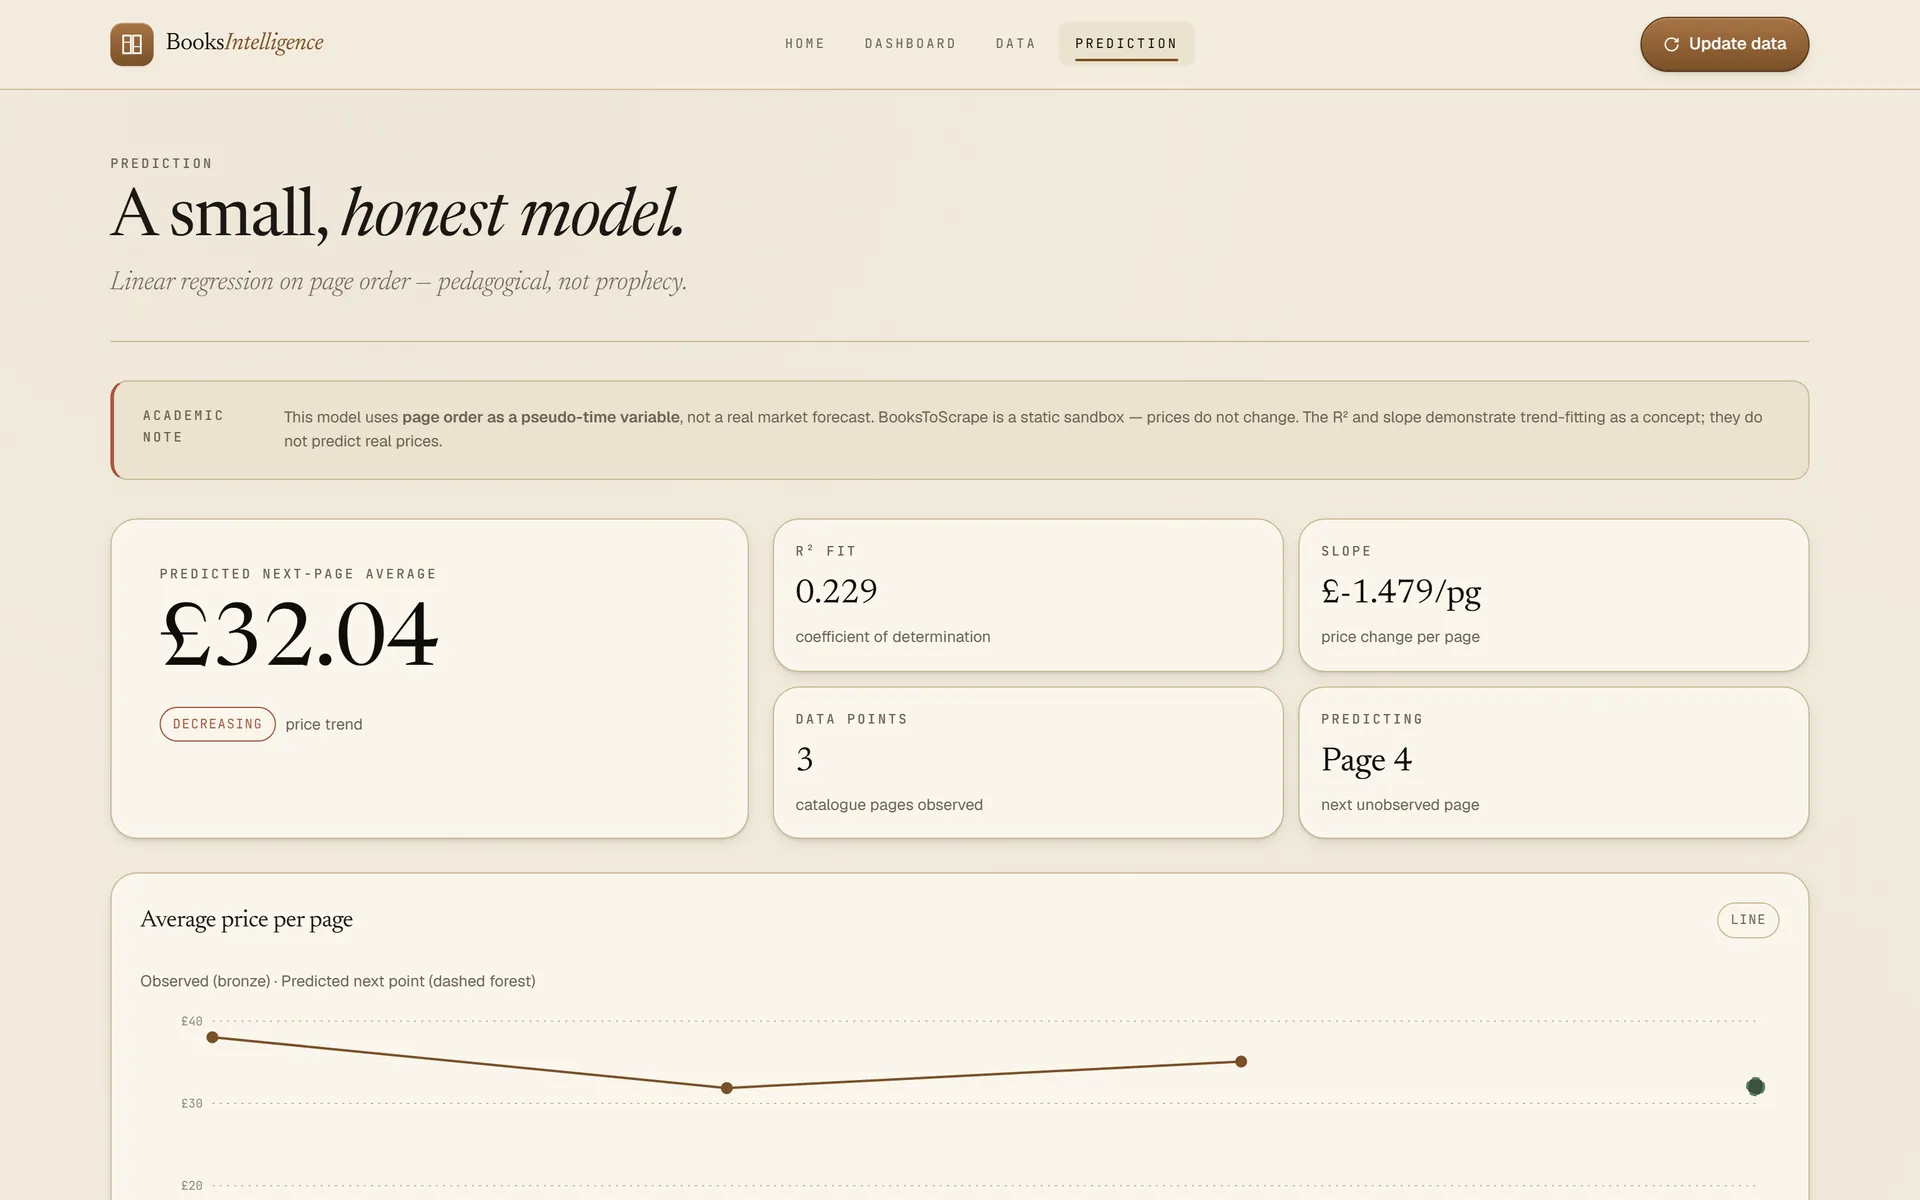
A scikit-learn regression framed honestly: page order as a pseudo-time variable, “pedagogical, not prophecy”.
Evidence